AI search vs traditional search: two mechanisms, and three systems rather than two
The short answer
AI search vs traditional search is usually framed as one comparison. It is two, and conflating them is why the advice contradicts itself.
The mechanism difference is real and simple. Traditional search crawls, indexes and ranks, then hands you a list to evaluate. AI search retrieves, augments and generates, then hands you a conclusion with citations attached. One gives you candidates. The other gives you an answer.
But the practical question is whether your rankings still buy you anything, and there the answer splits in two.
- On Google AI Overviews, ranking still helps and is helping less every month. Ahrefs found 38% of cited pages ranked in Google’s top 10 for the same query, down from 76% seven months earlier, across 863,000 keywords and four million AI Overview URLs.
- On assistants, ranking barely predicts citation at all. In a separate Ahrefs study of 15,000 queries, 12% of URLs cited by ChatGPT, Gemini and Copilot appeared in Google’s top 10. Perplexity was the outlier at 28.6%.
So there are three systems, not two, and Pepper scopes accounts that way. Classic results, AI Overviews sitting inside Google and leaning on its ranking, and assistants that mostly do not. A strategy built on “AI search versus SEO” will be right about one of those and wrong about the others.
Key takeaways
- Two mechanisms: crawl, index, rank against retrieve, augment, generate. The second is retrieval-augmented generation, and it is why citation rather than position is the unit.
- Three systems, not two. Treat AI Overviews and assistants as separate surfaces with separate evidence, because they behave differently.
- The top-10 overlap on AI Overviews halved in seven months, from 76% to 38%. Whatever number you learned last year is probably wrong now.
- Perplexity is the assistant most tied to conventional ranking, at 28.6% against roughly 6% to 9% for the others. Engine mix changes what your SEO is worth.
- Ranking is still necessary and no longer sufficient, which is the argument behind Pepper’s agentic organic growth engine rather than a reason to abandon search work.
A note on where this comes from. We run organic for more than 250 enterprises and track more than 10 million prompts across every major engine. The overlap figures below are Ahrefs’, dated and attributed. The three-system framing is ours, shaped by the strategy arguments we have in client reviews most weeks.
Book a growth audit if you want to know which of the three systems your buyers actually use before you rebalance anything.
What is the difference between AI search and traditional search?
Traditional search builds a result in three stages. A crawler fetches pages, an index stores and organises them, and a ranking system orders candidates against a query. The output is a list, and the user does the evaluating.
AI search builds an answer differently, through what is usually called retrieval-augmented generation. The system retrieves a set of candidate sources, augments the model’s context with what it found, and generates a single synthesised answer with citations. The output is a conclusion, and the system did the evaluating.
That difference produces the shift everyone describes correctly: from position to citation. There is no second place in an answer. You are named, cited, both or neither.
What this does not tell you is the useful part. Both descriptions are compatible with rankings mattering enormously or not at all, because retrieval is not the same as ranking and nobody publishes what retrieval uses. For that you need the overlap data, which is the next two sections.
If the vocabulary rather than the mechanism is the sticking point, the types of SEO in 2026 sorts the terms out. On whether this is one discipline or two, what Google settled is the page.
How much does ranking still buy you?
This is the number that should reorder most content plans, and it is the one the previous version of this page got closest to without sourcing.
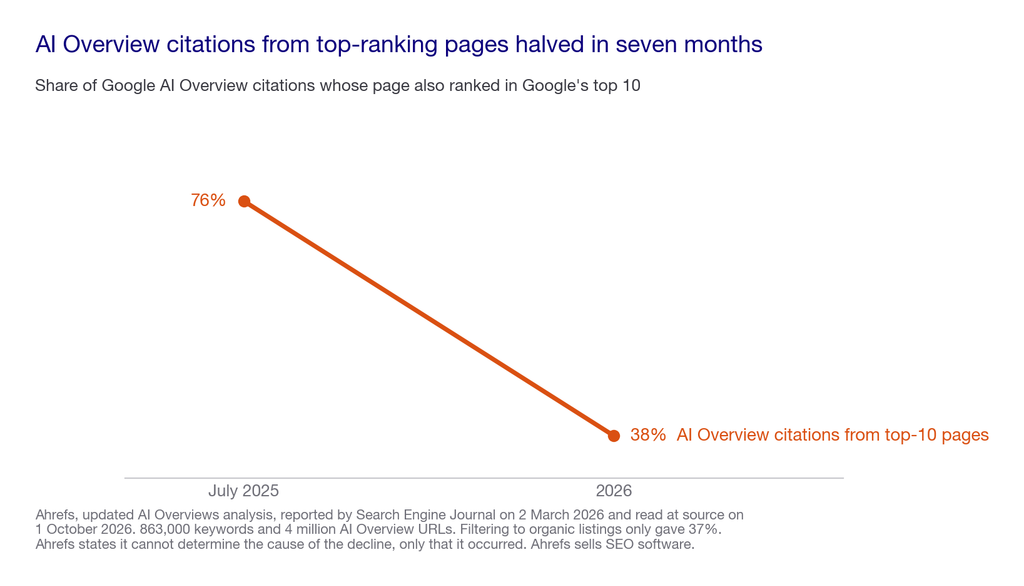
On Google AI Overviews, the link to conventional ranking is real and weakening fast. Ahrefs analysed 863,000 keywords and four million AI Overview URLs. It found that 38% of cited pages also ranked in Google’s top 10 for the same query. Seven months earlier the same measure was 76%. Filtering to organic listings only gave a near-identical 37%.
That is a halving in seven months. Not a trend you can extrapolate safely, and not one you can ignore either.
Two readings, and we hold both. Ranking into the top 10 still lifts your representation among AI Overview citations well above chance, so it is far from irrelevant. And a majority of cited pages now do not rank in the top 10, which was not true a year ago.
Where this falls short: this is Google’s own AI surface, measured by a vendor that sells SEO software. It says nothing directly about assistants, which is the next section. Ahrefs does not explain the cause of the decline either, only that it happened.
On assistants, the link is much weaker
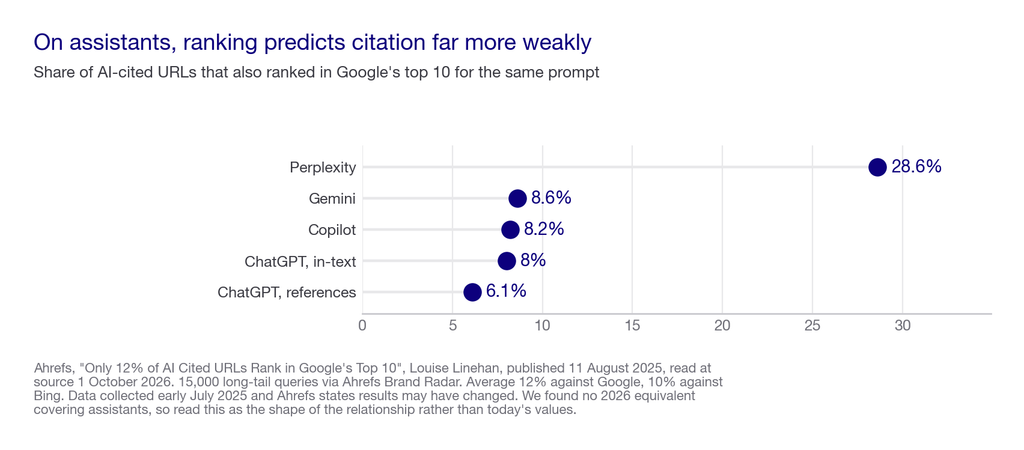
A separate Ahrefs study asked 15,000 long-tail queries of four assistants and compared the URLs they cited against what Google and Bing ranked for the same prompts.
| Assistant | Cited URLs ranking in Google’s top 10 |
|---|---|
| Perplexity | 28.6% |
| Gemini | 8.6% |
| Copilot | 8.2% |
| ChatGPT, in-text citations | 8.0% |
| ChatGPT, references | 6.1% |
| Average | 12% |
Against Bing’s top 10 the average was 10%, and across both engines 11%.
Perplexity is the outlier, and it matters commercially. Nearly one in three of its citations point at pages ranking in Google’s top 10. For ChatGPT it is closer to one in twelve. If your buyers use Perplexity, your rankings are worth several times more than if they use ChatGPT. That is an argument for knowing your engine mix before rebalancing anything.
Where this falls short, and it is a serious caveat: this data was collected in early July 2025. Ahrefs says so and adds that results may have changed. Given that the AI Overviews measure halved in the seven months after that, treat these figures as the shape of the relationship rather than today’s values. We could not find a 2026 equivalent covering assistants.
Three systems, not two
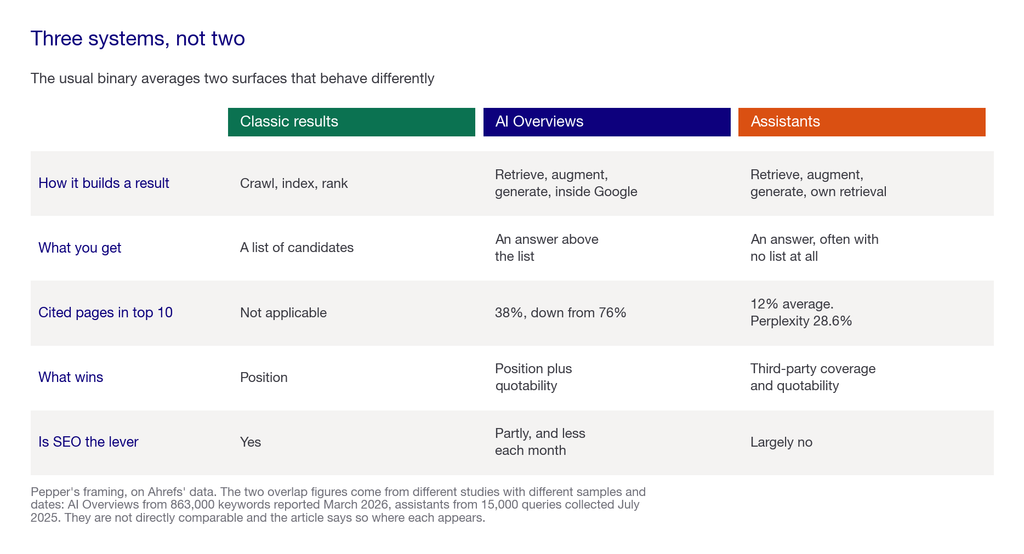
Put the two studies together and the usual binary falls apart. This is the framing Pepper uses when a client asks whether SEO still matters.
- Classic results are ranked by Google’s systems and your position is the whole game.
- AI Overviews sit inside Google, retrieve with help from its ranking, and cite from the top 10 about 38% of the time and falling.
- Assistants retrieve their own way and cite from the top 10 roughly 12% of the time, with Perplexity three times more ranking-dependent than ChatGPT.
The practical consequence is that “is SEO dead” has three answers and they conflict. For classic results, obviously not. For AI Overviews, still useful and depreciating. For assistants, largely beside the point, which is why the work that moves them is earned media and entity clarity rather than position.
A content plan that treats these as one surface over-invests in ranking for assistants and under-invests for AI Overviews. That is the most common misallocation we inherit.
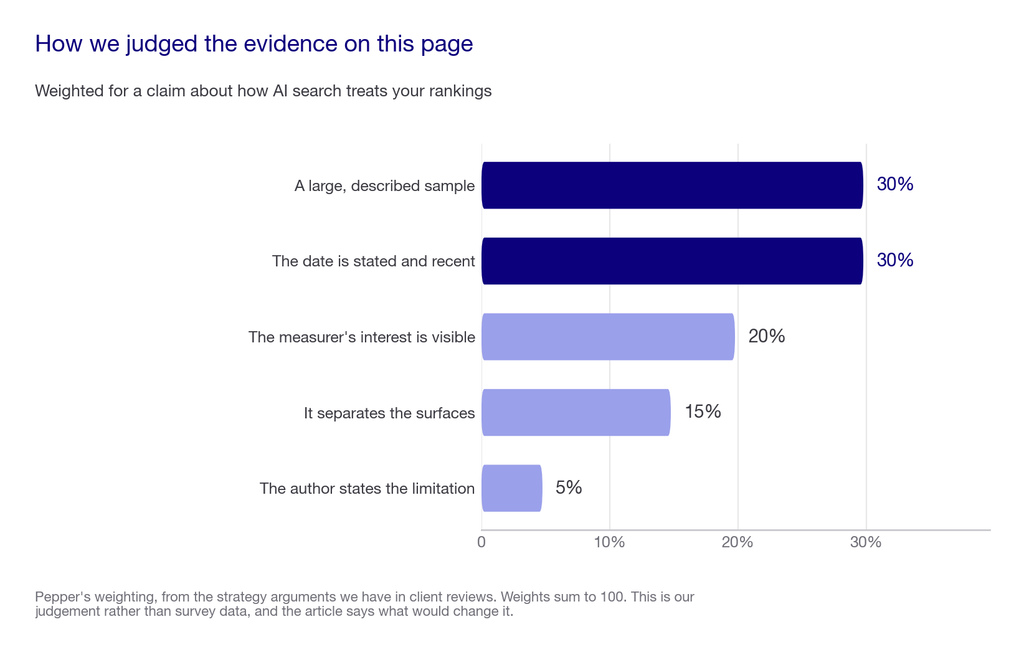
Our methodology: how we judged the evidence
| Criterion | Weight | Why it carries that weight |
|---|---|---|
| A large, described sample | 30 | 863,000 keywords and 15,000 queries are both big enough to act on. A study with no sample size is not evidence at whatever confidence it is quoted. |
| The date is stated and recent | 30 | The headline measure on this page halved in seven months. A figure without a collection date is unusable here more than almost anywhere. |
| The measurer’s interest is visible | 20 | Both studies are Ahrefs’, which sells SEO software and benefits from ranking mattering. Its data shows ranking mattering less, which is worth noting. |
| It separates the surfaces | 15 | A single figure for “AI search” averages two systems that behave differently and tells you nothing about either. |
| The limitation is stated by the author | 5 | Ahrefs says its assistant data may have changed and that it cannot explain the AI Overviews decline. That candour is a mark in its favour. |
Weights sum to 100. Sample and date carry 60 between them. That is Pepper’s judgement rather than a fact, and it is the judgement this page rests on. We publish our weightings the same way we publish [how we rank GEO agencies](https://www.pepper.inc/blog/geo-agency-ranking-methodology/), so you can argue with them precisely.
What would change these weights. A non-vendor study would drop the third criterion sharply. A 2026 dataset covering assistants would let us drop the caveat that currently sits on Figure 2.
The claims we removed
We are naming these rather than deleting them quietly, because the page carried them under a Pepper byline.
| Claim on the previous version | Why it is gone |
|---|---|
| Domain authority correlates with AI citation at r=0.18 | No source, and a correlation coefficient with no sample or method is not a finding |
| Statistics boost AI visibility by 22% | No source |
| Expert quotations boost AI visibility by 37% | No source |
| FAQ schema correlates with a 44% increase in citations | No source, and Google states structured data is not required for generative AI search |
| Pages under 5,000 characters extracted ~66% of the time, over 20,000 characters 12% | No source, and Google states there is no ideal page length |
| 96.55% of indexed pages get zero organic traffic | No source attached, and a figure to two decimal places needs one |
| 90% of ChatGPT citations from pages ranking 21+ | No source. Replaced by the Ahrefs figures, which say something similar with a method attached |
**The attributed statistics were a different problem: age.** SparkToro’s zero-click work was 2024, the Gartner projection was a February 2024 press release, and the Semrush and BrightEdge figures were 2025. On a measure that halved in seven months, a two-year-old number is not a baseline.
One terminology note. The previous version used “Share of Answer”. We use Share of Voice, our own dedicated page at that name is a known broken link, and adjacent phrasings sit on our banned-terms list. It has been replaced throughout.
AI search vs traditional search at a glance
| Classic results | AI Overviews | Assistants | |
|---|---|---|---|
| How a result is built | Crawl, index, rank | Retrieve, augment, generate, inside Google | Retrieve, augment, generate, own retrieval |
| Output | A list of candidates | An answer above the list | An answer, often with no list |
| Cited pages ranking top 10 | Not applicable | 38%, down from 76% | 12% average, Perplexity 28.6% |
| What wins | Position | Position plus quotability | Third-party coverage and quotability |
| Is SEO still the lever | Yes | Partly, and less each month | Largely no |
| Cost of misreading it | Low | Medium. Under-investing in a surface where ranking still pays | High. Over-investing in ranking for a surface that mostly ignores it |
## What this means for a content plan
- Do not stop doing SEO. Two of the three systems reward it, one of them heavily, and Google’s own guidance says optimising for generative AI search is still SEO.
- Stop expecting rankings to carry assistants. At roughly 12% overlap in mid-2025, and probably lower now, position is not the mechanism there.
- Check your engine mix before rebalancing. Perplexity being three times more ranking-dependent than ChatGPT is the difference between your SEO budget being well spent and being misdirected.
- Invest in the things that serve all three. Clear self-contained answers and third-party coverage help everywhere, which is covered in how to structure content for answer engines and in our statistics page.
- Measure by surface, not in aggregate. The GEO measurement stack sets out how, and why a single composite number hides exactly this split.
What this costs to get wrong
The changes this page argues for are mostly reallocations rather than new spend. The cost sits in the misallocation rather than in the fix.
- Over-investing in ranking for assistants. At roughly 12% overlap, a programme built on position is aimed at the wrong mechanism for that surface. This is the most expensive error we inherit.
- Cutting SEO on assistant data. The mirror of the same mistake, and worse, because two of the three surfaces still reward it and one of them is most of your traffic today.
- Reporting a blended figure. Free to produce and expensive to act on, because it hides the split this page is about.
- Checking your engine mix: free, and an afternoon. It is the single highest-return item here and almost nobody has done it.
Once the surfaces are named, our generative engine optimization cost benchmarks collects 30 published prices for the programme itself.
Where Pepper fits
We are an agentic organic growth engine, and the three-system framing is how we scope an account rather than a framework written for an article.
- An organic growth partner. A growth team is attached to your account, a senior strategist plus always-on agents, accountable for the number rather than for a ranking report.
- Pepper’s GEO platform. Genuinely self-serve and included rather than billed as a separate licence. You log in and set up a workspace. Define your brand profile, competitors and personas, then connect GA4 and Search Console. From there you manage your own themes, prompts and analytics across six engines, including ChatGPT, Perplexity, Gemini, Claude and Google AI Overviews.
- The Agent Atlas. Your team builds, versions and runs its own agents, and keeps them.
Reporting by surface is the practical version of this page. Brand Visibility and Domain Prompt Presence per engine, rather than one blended figure, is what shows you that your rankings are working on one system and not another. For what the combination produces, the Acceldata case study records 6X organic traffic and top-three keywords rising from 85 to more than 300, mostly through B2B SaaS programmes.
Where it falls short: we cannot tell you what any assistant’s retrieval actually uses, because none of them publishes it. We will not infer a mechanism from an overlap figure either. We are also not a technical SEO practice. If classic ranking has collapsed for technical reasons, that is somebody else’s job before it is ours.
How to choose what to change
I will write this in the first person, because a recommendation nobody will defend is worth nothing.
Start by refusing the binary. It is the first thing Pepper pushes back on in a strategy review. “AI search versus traditional search” invites a single answer to a question that has three, and every plan I have seen built on the binary over-corrects in one direction. The useful first move is to find out which of the three surfaces your buyers actually use, which takes an afternoon and changes the budget more than any framework.
So my order is: identify the surfaces, keep the SEO that serves two of them, and add the work that serves the third. Here is the scorecard I would use on any proposed change, on a 100 point scale.
| Area | Weight | What a change worth making demonstrates |
|---|---|---|
| It names which surface it serves | 30 | Classic, AI Overviews or assistants. A change that claims to serve all three usually serves none of them well. |
| The evidence behind it is dated | 25 | On this subject a 2024 figure describes a different world. Ask when the data was collected, not when the article was published. |
| It does not assume a retrieval mechanism | 20 | Nobody publishes how assistants retrieve. A tactic that depends on knowing is a guess with a price attached. |
| Your engine mix supports it | 15 | Perplexity and ChatGPT reward conventional ranking very differently. Check before rebalancing. |
| It is measurable by surface | 10 | A blended figure hides the split this page is about, so the reporting has to separate what the strategy separates. |
Five questions I would ask before changing a plan, in this order.
- “Which of the three surfaces are we talking about?” A stronger answer names one and cites evidence for that one. A weaker one says “AI search”, which averages two systems that disagree.
- “When was that data collected?” Not published, collected. The headline figure on this page halved in seven months.
- “Which engines do our buyers actually use?” This single check reorders more budgets than any argument about mechanism.
- “Are we cutting SEO based on assistant data?” If yes, stop. Two of the three surfaces still reward it and one of them is most of your traffic.
- “How will we see the difference by surface?” If the dashboard blends them, you will never know which change worked.
Red flags, each one something a supplier actually says. “SEO is dead”, which two of three surfaces contradict. A single overlap figure for “AI search” with no surface named. A correlation coefficient with no sample or method, which the previous version of this page carried. A tactic justified by how an assistant “decides”, when no assistant publishes that. And any guarantee of citations, which nobody can promise.
Before changing anything, measure your own split. Write 25 real commercial questions your buyers would type. Run each of those 25 prompts three times across every engine you care about, because engines are probabilistic and one run is an anecdote. Then give any fix 90 days before you judge it. Four worked examples for a mid-market B2B software company:
- “best data observability platform for enterprise”
- “how do I monitor data quality across Snowflake and Databricks”
- “what should I look for in a data observability vendor”
- “who competes with Monte Carlo in data observability”
Record which surface answered, and whether the cited pages are ones that rank for you. That is your own version of the Ahrefs overlap, on your category, and it is the only version that describes you.
And the answer that loses Pepper the sale. If your buyers are mostly still using classic Google results, you do not need an AI search programme this year, and you do not need us for one. Keep doing the SEO that works, and revisit when the mix moves.
It comes down to one principle: name the surface before you name the tactic. Every plan we have inherited that over-corrected, ours included on the page this one replaces, answered a three-part question with one number.
What nobody should promise you
- A single overlap figure for “AI search”. It averages two systems that behave differently, and the average describes neither.
- That SEO is dead. Two of the three surfaces reward it, and Google’s own guidance says optimising for generative AI search is still SEO.
- An explanation of how assistants retrieve. None of them publishes it. An overlap figure describes a relationship, not a mechanism.
- That these numbers will hold. The AI Overviews measure halved in seven months and the assistant data is from July 2025.
- A guaranteed citation. Engines are probabilistic and nobody controls their selection.
Frequently asked questions
What is the main difference between AI search and traditional search?
Traditional search crawls, indexes and ranks pages, then hands you a list to evaluate. AI search retrieves sources, augments a model’s context with them, and generates a single answer with citations. One gives you candidates, the other gives you a conclusion.
Does ranking number one on Google get me cited by AI?
Sometimes, and it depends entirely on the surface. Ahrefs found 38% of Google AI Overview citations came from top-10 ranking pages, down from 76% seven months earlier. For assistants the average was 12%, with Perplexity highest at 28.6%.
What is retrieval-augmented generation?
It is the method behind most AI search. The system retrieves candidate sources for a query, adds what it found to the model’s context, then generates an answer citing them. It explains why citation rather than ranking position is the unit of visibility.
Is SEO dead because of AI search?
No, and the question has three answers. For classic results SEO is the whole game. For AI Overviews it still helps and helps less each month. For assistants it is largely beside the point, where earned media and entity clarity matter more.
Which AI engine relies most on Google rankings?
Perplexity, by a wide margin. Ahrefs found 28.6% of its citations pointed at pages ranking in Google’s top 10. Gemini and Copilot were near 8%, and ChatGPT between 6% and 8%, on data collected in July 2025.
Why did AI Overview citations from top-ranking pages fall?
Ahrefs reports the drop from 76% to 38% and states plainly that it cannot determine the cause, only that it happened. Anyone offering you a confident explanation for the decline is going beyond the published evidence.
How should I split effort between SEO and AI search work?
Check which of the three surfaces your buyers use first. Keep the SEO that serves classic results and AI Overviews, and add third-party coverage and quotable answers for assistants, which conventional ranking mostly does not reach.
How do I measure visibility across both?
By surface rather than in aggregate. Track how often each engine names you, and how often it cites a page from your domain, on a frozen prompt set. A single blended score hides exactly the split this page describes.
Where to go next
If the vocabulary is the confusion, our map of the search optimisation terms sorts them out, and the AEO against SEO head-to-head covers whether this is one discipline or two.
Once the framing is clear, the passage craft guide covers the writing and the three tiers of hidden content covers whether a crawler can read you at all. The reporting side sits in measuring visibility by surface.
Sources and further reading
- Ahrefs, updated AI Overviews analysis, reported by Search Engine Journal, Matt G. Southern, published 2 March 2026 and read at source on 1 October 2026. 863,000 keywords and four million AI Overview URLs. 38% of cited pages ranked in Google’s top 10 for the same query, down from 76% in July 2025. Filtering to organic listings only gave 37%. Ahrefs does not explain the cause of the decline, only that it occurred. Ahrefs sells SEO software.
- Ahrefs, “Only 12% of AI Cited URLs Rank in Google’s Top 10 for the Original Prompt”, Louise Linehan, data science by Xibeijia Guan, published 11 August 2025, read at source on 1 October 2026. 15,000 long-tail queries via Ahrefs Brand Radar, comparing citations from ChatGPT, Gemini, Copilot and Perplexity against Google and Bing top-10 rankings. Perplexity 28.6%, Gemini 8.6%, Copilot 8.2%, ChatGPT in-text 8.0%, ChatGPT references 6.1%, average 12% against Google and 10% against Bing. Data collected in early July 2025, and Ahrefs states results may have changed. We could find no 2026 equivalent covering assistants, and this page says so where the figures appear.
- Google Search Central, “Optimizing your website for generative AI features on Google Search”, last updated 10 July 2026. The position that optimizing for generative AI search is still SEO, and the statements that structured data is not required and there is no ideal page length, both of which bear on removed claims.
A note on the statistics that are not here. Seven claims from the previous version were removed for having no source, including a correlation coefficient, three percentage lifts and two extraction rates quoted by character count. Several attributed figures were dropped for age rather than accuracy: a 2024 zero-click study, a February 2024 Gartner projection, and 2025 figures on AI Overview prevalence. On a measure that halved in seven months, a two-year-old number is not a baseline.
Further reading on Pepper, each checked live on 1 October 2026:
- Types of SEO, sorted by what kind of thing each one is, if the vocabulary is the problem.
- Answer engine work against search work, whether this is one discipline or two.
- Which KPIs actually mean anything, measuring by surface rather than in aggregate.
- AI search statistics that hold up in 2026, the adoption numbers with their samples attached.
A note on scope and on corrections. This page covers the mechanism and the evidence on how much ranking still buys. It does not settle whether AI search is a separate discipline, which the AEO against SEO page covers, and it does not re-explain the vocabulary. The structural argument from the previous version is kept, because it was right. Seven unsourced statistics were removed and several attributed ones were dropped for age. “Share of Answer” was replaced with Share of Voice, and a named reviewer was added where the previous version had none.
Latest Blogs
Most advice on this is inference dressed as fact. OpenAI documents exactly one thing clearly, which is access. Here is what is documented, what is inferred, and how to verify the rest for yourself.
Being named in an AI answer and having your page used as its source are different outcomes with different causes and different fixes. The gap between them is the most useful diagnostic in AI search, and most reporting collapses it into one number.
Every platform reports share of voice and almost none of them define it the same way. Here is the definition worth using, the three choices that change the number, and how to measure it yourself without buying anything.
Get your hands on the latest news!
Similar Posts
GEO / AI Search
10 mins read
How to get cited by ChatGPT
GEO / AI Search
10 mins read
Mentioned vs cited: the difference that decides AI visibility
GEO / AI Search
13 mins read