How to rank in Google AI Overviews: what Google documents, and what it says you can skip
The short answer
Google documents what AI Overviews need, and it is shorter and duller than most playbooks admit.
Its page on AI features states the position plainly: “You don’t need to create new machine readable files, AI text files, or markup to appear in these features. There’s also no special schema.org structured data that you need to add.” The same page says no special action is required. It points you at the foundational SEO practices you already know.
What it does document, and what almost nobody builds around, is query fan-out. Google describes AI Overviews and AI Mode as “issuing multiple related searches across subtopics and data sources”. The stated purpose is to “display a wider and more diverse set of helpful links”.
That single mechanism explains the thing everyone is confused about. Ahrefs found only 38% of pages cited in AI Overviews also ranked in Google’s top 10 for the same query. Seven months earlier it was 76%. If the system is searching subtopics you never targeted, the page that gets cited is often answering a question you did not write the page for.
So the playbook is not schema. It is coverage of the sub-questions around your query, on pages a crawler can read, and that is how Pepper scopes this surface.
Key takeaways
- Google says no special markup and no special schema. Quoted verbatim, from its own page on AI features, last updated 10 December 2025.
- Query fan-out is the mechanism worth designing for. Google issues multiple related searches across subtopics, so the winning passage often answers a sub-question rather than the headline query.
- Ranking still helps and helps less each month. 38% of cited pages ranked top 10, against 76% seven months earlier.
- Prevalence figures disagree by three times because the datasets disagree: roughly 15%, 30% and 48% depending on whose sample you use. The previous version of this page quoted the highest one as a fact.
- Commercial intent is where the growth is. Semrush found AI Overviews on commercial SERPs grew 71% in six months, while transactional SERPs fell 5%. That is why Pepper’s agentic organic growth engine treats this as a mid-funnel problem.
A note on where this comes from. We run organic for more than 250 enterprises and track more than 10 million prompts across every major engine. The Google quotations are Google’s, the two studies are Ahrefs’ and Semrush’s, all dated and attributed. The playbook that follows is our judgement, labelled as such.
Book a growth audit if you want to know which of your pages AI Overviews already cite before you commission anything.
What is an AI Overview, and how does it pick a source?
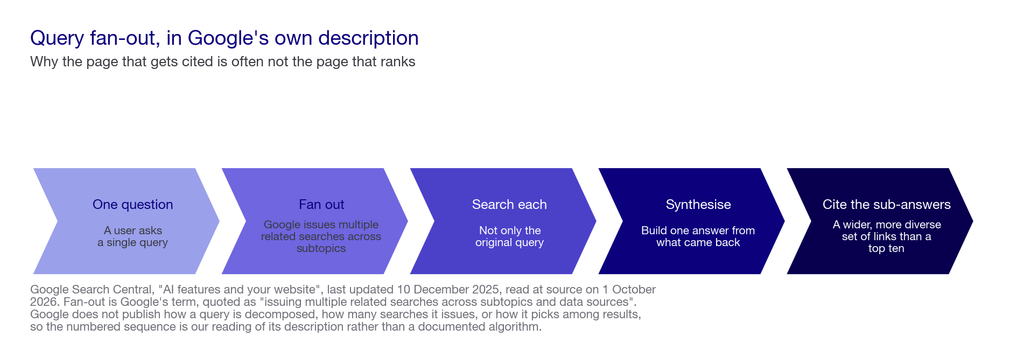
Google describes the mechanism for both AI Overviews and AI Mode in one phrase: “query fan-out”. It defines that as “issuing multiple related searches across subtopics and data sources”, to develop a response and to “display a wider and more diverse set of helpful links”.
Read that as a process and the implications fall out.
- A user asks one question.
- Google decomposes it into related sub-questions across subtopics and data sources.
- It searches each of those sub-questions separately, alongside the original query.
- It synthesises an answer from what those searches returned.
- It cites the pages that answered the sub-questions, which is why the citation list looks wider and more diverse than a top-10.
This is the reason the overlap with conventional ranking is falling. Ahrefs analysed 863,000 keywords and four million AI Overview URLs and found 38% of cited pages also ranked in Google’s top 10 for the same query. Seven months earlier that figure was 76%. Filtering to organic listings only gave 37%.
So the unit of competition is not your page against the top 10 for one query. It is whether some passage of yours answers one of the sub-questions Google decided to ask. That is a coverage and writing problem, not a markup one.
Where this falls short: Google describes fan-out and publishes nothing about how it decomposes a query. Not the number of sub-searches, not how it picks among results. Anyone offering a fan-out method with specific numbers is going well beyond the documentation.
What Google says you can skip
The previous version of this page built its playbook on schema, with specific lift percentages for FAQPage, HowTo, Organization and Person markup.
Google’s page on AI features addresses this directly, quoted verbatim: “You don’t need to create new machine readable files, AI text files, or markup to appear in these features. There’s also no special schema.org structured data that you need to add.”
Its separate guide to generative AI features goes further, and we counted the statements when we reviewed it. Five things it says you do not need. Chunking content into tiny pieces, machine-readable files or Markdown, a special writing style for AI, structured data, and an ideal page length. Three things it asks for. Write well for a human audience, with clear paragraphs, sections and headings. Add good images and video. Create content yourself from what you know.
We still keep FAQPage and Article schema on client sites. It earns rich results and helps entity clarity. We stopped selling it as an AI Overview citation lever. We would push back on anyone who does, because Google says in writing that it is not required.
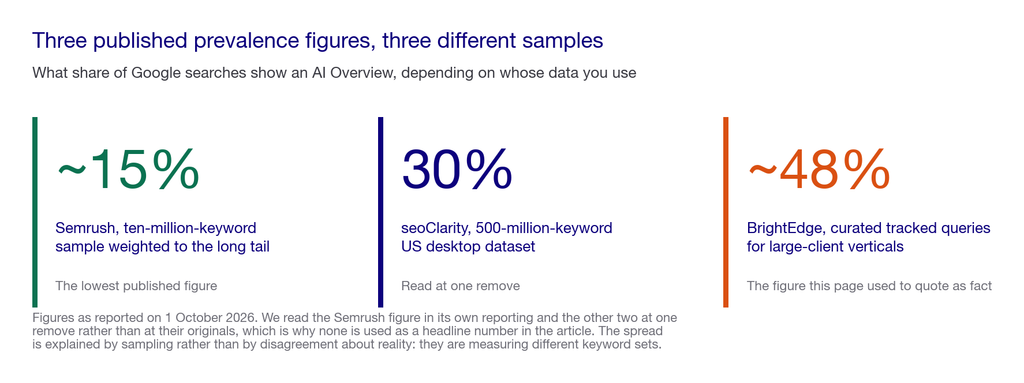
On prevalence, the previous version quoted 48% of queries as a flat fact. Published figures range widely because the samples do.
- Around 15%, on Semrush’s ten-million-keyword sample, which skews to the long tail.
- 30%, on seoClarity’s 500-million-keyword US desktop dataset.
- Around 48%, on BrightEdge’s curated tracked queries for large-client verticals.
Three methods, three answers, and the page picked the most flattering one. We read the Semrush figure in its own reporting and the other two at one remove. That is why none appears here as a headline number.
Where AI Overviews are actually growing
Prevalence in aggregate is less useful than prevalence by intent, and there the evidence is clearer and recent.
Semrush analysed more than 600,000 keywords from its US desktop database between November 2025 and April 2026, segmented by industry, intent and cost per click.
- Commercial-intent SERPs with an AI Overview grew 71% over the six months.
- Transactional-intent SERPs fell 5%.
- Google Ads and AI Overviews now appear together about twice as often as a year earlier.
Read as a planning signal, that is specific and useful. The surface is expanding fastest exactly where buyers compare options, which is where most B2B content sits. It is contracting slightly where they are ready to buy.
Stated limitation, from Semrush: Google Ads does not reveal which paid queries trigger AI Overviews, so there is a real visibility gap for paid teams.
How to rank in Google AI Overviews: the playbook, in Google’s order
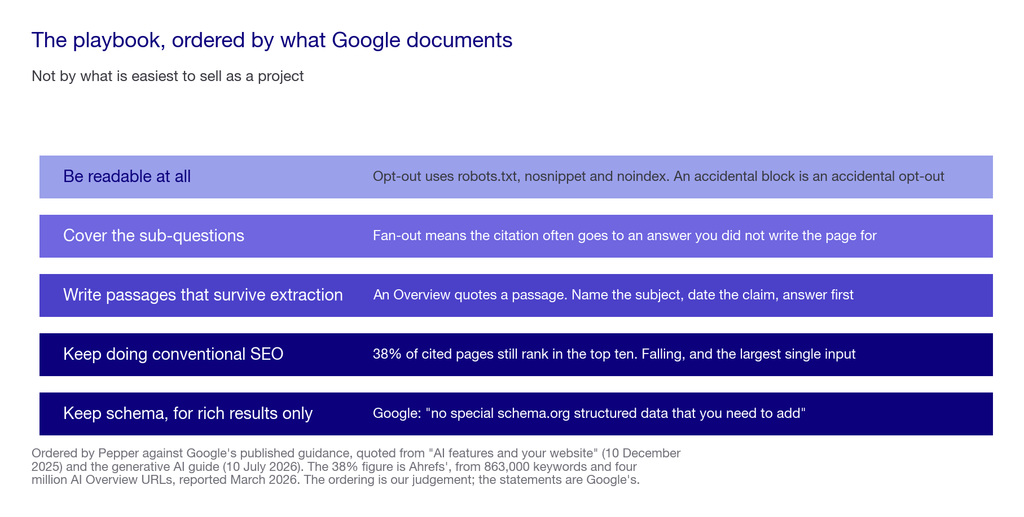
1. Be readable before anything else
If a crawler cannot receive your text, nothing else on this list matters. Google’s opt-out controls for these features are the ones you already know: robots.txt for Googlebot, plus nosnippet, data-nosnippet, max-snippet and noindex. So an accidental block is an accidental opt-out.
Check those first, along with whether your answers survive rendering at all, which our guide to what a crawler receives covers properly.
2. Cover the sub-questions as well as the query
This is the fan-out implication, and it is the part that differs from classic SEO. It is also the step Pepper adds to a standard content brief. For any query you care about, write down the five to ten questions a reader would ask around it. Then make sure some page of yours answers each one, in a passage that stands alone.
You are not trying to rank one page for one query. You are trying to be the best answer to one of several sub-questions. That is a wider and shallower brief than most content plans assume.
3. Write passages that survive extraction
An AI Overview quotes a passage, not a page. Name the subject in the first sentence. Put the date and the unit inside the claim, and answer before you explain. The passage craft guide covers the six rules properly.
4. Keep doing conventional SEO
At 38% overlap and falling, ranking is no longer the whole story. It is still the largest single input, and Google’s own guidance says optimising for generative AI search is still SEO. Nothing on this page is a reason to cut it.
5. Keep schema, for the reasons it actually works
Rich results, entity clarity, accurate structured data as Google recommends. Not as a citation lever, because Google says there is no special schema for these features.
Our methodology: how we ordered the playbook
| Criterion | Weight | Why it carries that weight |
|---|---|---|
| Google documents it | 35 | The only engine publishing guidance for this surface. If Google says a thing is not required, we do not sell it as required. |
| It follows from a documented mechanism | 25 | Fan-out is described by Google, so covering sub-questions is a reasonable inference. Specific fan-out tactics are not. |
| Independent evidence supports it | 20 | The Ahrefs and Semrush studies, with their samples and dates. Vendor research, disclosed as such. |
| It helps on other surfaces too | 15 | Readability and quotable passages help everywhere. A tactic that only helps AI Overviews is a narrow bet on one surface. |
| It is cheap to apply | 5 | Most of this list is editorial discipline rather than engineering, which is why the schema project is the wrong first move. |
Weights sum to 100. Documentation and documented mechanism carry 60 between them. That is Pepper’s judgement rather than a fact, and it is the judgement this page rests on. We publish our weightings the same way we publish [how we rank GEO agencies](https://www.pepper.inc/blog/geo-agency-ranking-methodology/), so you can argue with them precisely.
What would change these weights. If Google published anything about how fan-out decomposes a query, the second criterion would carry far more and this page would need rewriting rather than updating.
The claims we removed
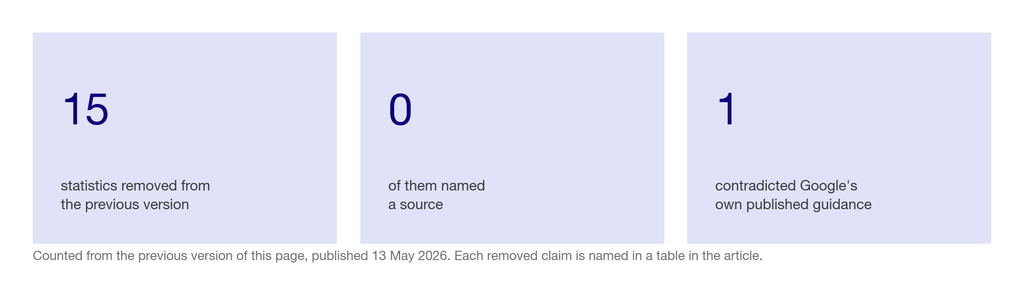
We are naming these rather than deleting them quietly, because the page carried them under a Pepper byline and readers may have acted on them.
| Claim on the previous version | Why it is gone |
|---|---|
| FAQPage schema gives a 3.2x likelihood boost and 28% higher citation rates | No source, and Google states there is no special schema needed for these features |
| Organization and Person schema gave a 19.72% visibility lift | No source. A figure to two decimal places needs one |
| Multimodal content achieves 317% higher selection rates | No source. The same unsourced figure appears on at least one other Pepper page |
| AI Overviews on ~48% of queries, up 58% year on year | No source, and it is the highest of three published figures that range from about 15% to 48% |
| Industry rates of 82%, 83% and 78% | No source |
| Top-ranked pages lose 34.5% CTR on average | No source |
| Citations yield up to a 35% CTR lift | No source |
| 96% of AI Overview citations come from authoritative sources | No source, and “authoritative” is undefined |
| PlushBeds 753% LLM traffic surge and 950% AI Overview lift | No source, and it names a company. A named client result with no attribution is the most serious version of this problem |
| A manufacturer’s 2,300% AI referral lift, and CPRologist’s 42 citations and 532% growth | Same |
| 37.1% of AI-cited pages ranked top 10, 36.7% beyond position 100, across 863,000 keyword SERPs | This one is real and was uncredited. It is Ahrefs’ data, now cited properly with its date and sample |
One terminology note. The page is titled “how to rank in AI Overviews” because that is what people search for, and we have kept the URL. There is no ranking in an AI Overview.You are cited or you are not, and the article uses the accurate verb throughout while the title matches the query.
AI Overviews at a glance
| What | Google’s published position | What to do | Cost of getting it wrong |
|---|---|---|---|
| Special markup or AI files | “You don’t need to create new machine readable files, AI text files, or markup” | Nothing | Medium. A project that buys nothing |
| Special schema | “There’s also no special schema.org structured data that you need to add” | Keep schema for rich results only | Medium. Same |
| Query fan-out | Documented, as “issuing multiple related searches across subtopics” | Cover the sub-questions around your query | High. This is the mechanism most plans ignore |
| Crawlability | Same technical requirements as Search | Check robots.txt and rendering first | Highest. The opt-out controls are the ones you already use |
| Conventional ranking | Same foundational practices | Keep doing it | High. 38% overlap is still the largest single input |
| Content quality | “Helpful, reliable, people-first content” | Write for the reader, with first-hand experience | Medium |
| Opting out | robots.txt, nosnippet, data-nosnippet, max-snippet, noindex | Know these exist before someone applies one | High. An accidental block is an accidental opt-out |
What this costs
- The readability check: free, about ten minutes a template. View-source against rendered DOM, plus a look at robots.txt and your CDN rules.
- Sub-question coverage: editorial time, not budget. Five to ten questions per priority topic, harvested from sales calls rather than a keyword tool.
- Passage rewriting: roughly ten minutes per 1,500 words once a writer has the habit.
- What you should not pay for: a schema project sold as an AI Overviews lever. Google’s own documentation says it is not required, and that sentence is one click away.
For what a full programme costs, our generative engine optimization cost benchmarks collects 30 published prices.
Where Pepper fits
We are an agentic organic growth engine, and on this surface our honest position is that most of the work is ordinary SEO done properly.
- An organic growth partner. A growth team is attached to your account, a senior strategist plus always-on agents, accountable for the number rather than for a schema audit.
- Pepper’s GEO platform. Genuinely self-serve and included rather than billed as a separate licence. You log in and set up a workspace. Define your brand profile, competitors and personas, then connect GA4 and Search Console. From there you manage your own themes, prompts and analytics across six engines, including Google AI Overviews, ChatGPT, Perplexity, Gemini and Claude.
- The Agent Atlas. Your team builds, versions and runs its own agents, and keeps them.
Themes in the platform are the sub-question layer made trackable, which is the practical answer to fan-out. You cannot target a decomposition Google does not publish. You can cover a topic thoroughly enough that some passage of yours answers whatever it asks. For what that produces, the Acceldata case study records 6X organic traffic and top-three keywords rising from 85 to more than 300, mostly through B2B SaaS programmes.
Where it falls short: we cannot tell you how Google decomposes a query, because Google does not publish it. We will not sell a fan-out method built on guesswork either. We are also not a technical SEO practice, so if the finding is a rendering problem, we will identify it and somebody else will fix it. And this page removes fifteen statistics from our own work, which is the clearest evidence that our published playbooks need the same scrutiny we apply to suppliers.
How to choose what to do first
I will write this in the first person, because a recommendation nobody will defend is worth nothing.
Start by finding out whether AI Overviews cite you at all, and for which queries. It is the first thing Pepper checks before scoping this work. Most teams asking how to appear in them have never checked, and the answer changes the work entirely. If you are cited regularly, the job is protecting and extending that. If you are never cited where an Overview appears, the job is usually coverage or readability.
So my order is: check citations, check readability, then widen coverage. Here is the scorecard I would use on any proposed tactic, on a 100 point scale.
| Area | Weight | What a tactic worth doing demonstrates |
|---|---|---|
| Google’s documentation supports it | 35 | A link to Google’s own page. This surface is the one case where the engine publishes guidance, so there is no excuse for guessing. |
| It addresses coverage or readability | 25 | The two things fan-out and crawling actually reward. A tactic aimed at neither is aimed at a mechanism nobody has published. |
| Evidence exists with a sample and date | 20 | The Ahrefs and Semrush figures qualify. A percentage with no study behind it does not, however confidently it is quoted. |
| It helps on other surfaces | 15 | Assistants do not read schema either. Work that only serves AI Overviews is a narrow bet. |
| It does not need engineering | 5 | Most of the real list is editorial. If the proposal starts with a platform change, ask why. |
Five questions I would ask before funding anything, in this order.
- “Where does Google say this?” A stronger answer opens a Google page. A weaker one cites a percentage, which is what the previous version of this page did fifteen times.
- “Which sub-questions does this cover?” Fan-out means the citation often goes to a sub-answer. If nobody can list the sub-questions, the plan is aimed at the headline query only.
- “Can a crawler read our answer?” View-source, not the rendered page. This resolves more cases than anything else.
- “Are we already cited, and where?” Check before commissioning. It reorders the work.
- “Would we do this if AI Overviews vanished?” If yes, it is real work. If no, ask question one again.
Red flags, each one something a supplier actually says. “Add FAQPage schema to get cited in AI Overviews”, which Google’s own documentation contradicts. A prevalence figure with no sample named. A named client result with no attribution. A fan-out optimisation method with specific numbers, when Google publishes none. And any guarantee of citations, which nobody can promise.
Before commissioning anything, measure. Write 25 real commercial questions your buyers would type. Run each of those 25 prompts three times in Google, because engines are probabilistic and one run is an anecdote. Then give any fix 90 days before you judge it. Four worked examples for a mid-market B2B software company:
- “best data observability platform for enterprise”
- “how do I monitor data quality across Snowflake and Databricks”
- “what should I look for in a data observability vendor”
- “who competes with Monte Carlo in data observability”
Record whether an Overview appeared, who it cited, and whether those pages rank. That last column is your own version of the Ahrefs overlap, and it tells you how much your SEO is currently buying you on this surface.
And the answer that loses Pepper the sale: if AI Overviews rarely appear for your queries, you do not need this playbook and you do not need us for it. On the lowest published prevalence figure that is most long-tail queries, so check before you spend.
It comes down to one principle: cover the sub-questions on pages a crawler can read, and refuse the markup upsell. The previous version of this page sold the upsell, ours included in the count of people who should have read Google’s documentation first.
What nobody should promise you
- That schema gets you into AI Overviews. Google states there is no special structured data you need to add.
- A reliable prevalence figure. Published numbers range from roughly 15% to 48% depending on the sample.
- A fan-out optimisation method. Google describes fan-out and publishes nothing about how it decomposes a query.
- A guaranteed citation. Engines are probabilistic and nobody controls their selection.
- That ranking no longer matters here. At 38% overlap it is still the largest single input, even while falling.
Frequently asked questions
How do I rank in Google AI Overviews?
There is no ranking in an AI Overview, only citation. Google says no special markup or schema is needed. What helps is being crawlable, covering the sub-questions around your topic, and writing passages that stand alone when quoted.
Does schema markup help with AI Overviews?
Not for citation. Google’s own page states plainly that there is no special schema.org structured data you need to add to appear in these features. Keep schema for rich results and entity clarity, and stop buying it as an AI Overview lever.
What is query fan-out?
Google’s term for how AI Overviews and AI Mode work: issuing multiple related searches across subtopics and data sources to build a response and surface a wider set of links. It is why cited pages often answer a sub-question rather than your headline query.
Do I still need to rank on page one?
It helps and helps less than it did. Ahrefs found 38% of pages cited in AI Overviews also ranked in Google’s top 10 for the same query. Seven months earlier it was 76%, across 863,000 keywords and four million URLs.
What percentage of searches show an AI Overview?
It depends whose sample you use. Published figures range from around 15% on a long-tail-weighted sample, to 30% on a large US desktop dataset, to around 48% on curated client verticals. Treat any single figure sceptically.
Are AI Overviews growing?
On commercial queries, yes. Semrush found commercial-intent SERPs with an AI Overview grew 71% between November 2025 and April 2026, across more than 600,000 keywords, while transactional-intent SERPs fell 5% over exactly the same period.
Can I opt out of AI Overviews?
Yes, using controls you already have: robots.txt directives for Googlebot, plus nosnippet, data-nosnippet, max-snippet and noindex. That also means an accidental block somewhere in your stack is an accidental opt-out that nobody actually decided.
Why did my page get cited when it does not rank?
Most likely query fan-out. Google decomposed the question into subtopics and searched those separately, and your page was the best answer to one of them, even though it does not rank for the original query.
Where to go next
If the constraint is that crawlers cannot read your answers, the three tiers of hidden content covers what a crawler actually receives. If they can and you are still not cited, the passage craft guide is the next constraint.
For how this surface compares with assistants, the three systems and the evidence is the companion page. To measure any of it, the GEO measurement stack covers which KPIs mean anything.
Sources and further reading
- Google Search Central, “AI features and your website”, last updated 10 December 2025, read at source on 1 October 2026. All quotations are verbatim. On markup: “You don’t need to create new machine readable files, AI text files, or markup to appear in these features. There’s also no special schema.org structured data that you need to add.” On mechanism: AI Overviews and AI Mode use “query fan-out”, described as “issuing multiple related searches across subtopics and data sources” to “display a wider and more diverse set of helpful links”. Opt-out controls named: robots.txt for Googlebot, plus
nosnippet,data-nosnippet,max-snippetandnoindex. Google does not publish how a query is decomposed. - Google Search Central, “Optimizing your website for generative AI features on Google Search”, last updated 10 July 2026. Five statements about what is not required, three about what to do, counted by us when we reviewed the guide.
- Ahrefs, updated AI Overviews analysis, reported by Search Engine Journal, Matt G. Southern, 2 March 2026. 863,000 keywords and four million AI Overview URLs. 38% of cited pages ranked in Google’s top 10 for the same query, down from 76% in July 2025; 37% filtering to organic listings only. Ahrefs states it cannot determine the cause of the decline. Ahrefs sells SEO software. Not hyperlinked, per our policy on vendor links.
- Semrush, “AI Overviews are expanding across commercial intent search”, Luke Harsel with Anna Yudina and Christine Skopec, published 2 July 2026, read at source on 1 October 2026. More than 600,000 keywords from the Semrush US desktop database, November 2025 to April 2026, segmented by industry, intent and CPC. Commercial-intent SERPs with an AI Overview grew 71%; transactional fell 5%; Ads and AI Overviews co-appear about twice as often as a year earlier. Stated limitation: Google Ads does not reveal which paid queries trigger AI Overviews. Semrush sells an AI visibility toolkit. Not hyperlinked, per our policy on vendor links.
- On prevalence figures. Roughly 15% on Semrush’s ten-million-keyword long-tail-weighted sample, 30% on seoClarity’s 500-million-keyword US desktop dataset, and around 48% on BrightEdge’s curated tracked queries for large-client verticals. We read the second and third at one remove rather than at their originals. That is why none is used as a headline number here, and why the article presents the range rather than a figure.
Further reading on Pepper, each checked live on 1 October 2026:
- What a crawler actually receives, and whether your answer is in the served HTML.
- How to structure content for answer engines, the passage craft.
- AI search against traditional search, how this surface compares with assistants.
- The GEO measurement stack, which KPIs mean anything.
Latest Blogs
Most advice on this is inference dressed as fact. OpenAI documents exactly one thing clearly, which is access. Here is what is documented, what is inferred, and how to verify the rest for yourself.
Being named in an AI answer and having your page used as its source are different outcomes with different causes and different fixes. The gap between them is the most useful diagnostic in AI search, and most reporting collapses it into one number.
Every platform reports share of voice and almost none of them define it the same way. Here is the definition worth using, the three choices that change the number, and how to measure it yourself without buying anything.
Get your hands on the latest news!

Similar Posts
GEO / AI Search
10 mins read
How to get cited by ChatGPT
GEO / AI Search
10 mins read
Mentioned vs cited: the difference that decides AI visibility
GEO / AI Search
13 mins read