How to audit your site for AI search: a 12 point checklist
The short answer
An AI search visibility audit is a technical check on whether engines can reach your pages, read them, and lift an answer out of them.
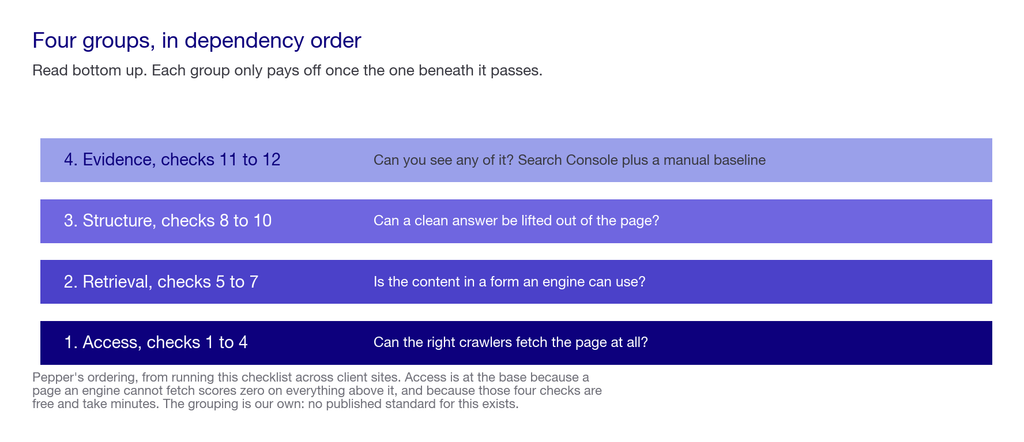
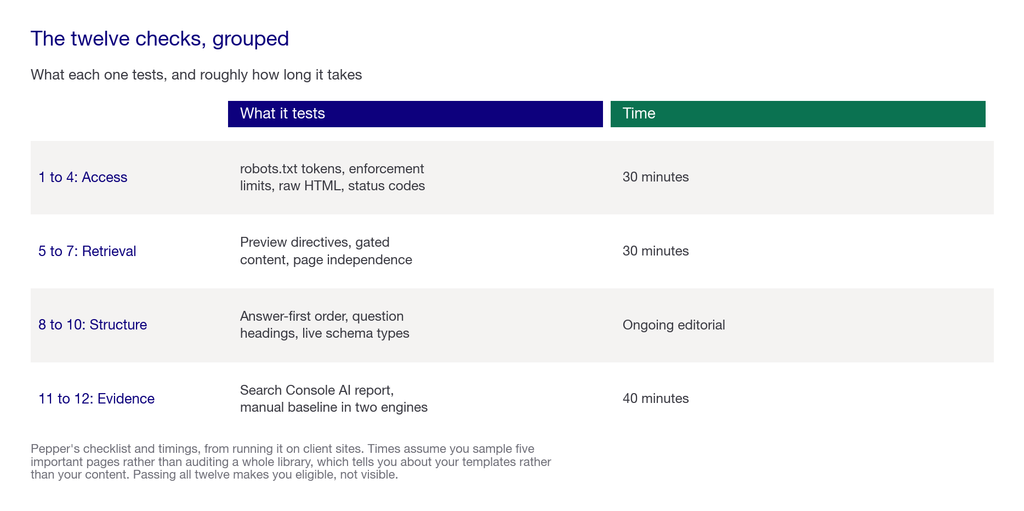
It splits into four groups, and they are sequential rather than parallel.
- Checks 1 to 4, access. Can the right crawlers fetch your pages at all. Free, fast, and if any of these fail, nothing below them counts.
- Checks 5 to 7, retrieval. Does your content exist in a form an engine can actually use.
- Checks 8 to 10, structure. Can a clean answer be lifted out of the page.
- Checks 11 to 12, evidence. Are you measurable, and are you measuring.
This is the on-site half of the job. The strategic audit, which looks at competitors, citation sources and where the gaps are, is a different exercise and we cover it in how to run a GEO and AI visibility audit. Four of that audit’s five stages look outside your own site. This page is the one stage that looks inward, done properly.
We run this work daily. Pepper is an agentic organic growth engine, not an SEO agency. This page comes out of what we run: organic for more than 250 enterprises across eight years, more than 10 million tracked prompts, and the questions buyers put to us in client reviews. Customers log in and run the platform themselves, with a Pepper growth team attached. Book a growth audit and we will run this against your site with you.
Key takeaways
Key takeaways from running this checklist across client sites.
- Search crawlers and training crawlers are different agents. Blocking the wrong token removes you from answers you meant to appear in.
- One fetcher ignores robots.txt entirely. Perplexity states its user-triggered fetcher “generally ignores robots.txt rules.”
- Preview directives can suppress you quietly. An aggressive
max-snippetset years ago limits your appearance in Google’s AI features. - Soft 404s are a real and invisible problem. A missing page returning HTTP 200 with an error in the body poisons crawling, and it is common.
- Two schema types are dead weight. Google no longer shows FAQ or HowTo rich results.
- The whole checklist is free. Every check below uses your own site, a browser and Search Console.
What is an AI search visibility audit, and what does it cover?
An AI search visibility audit checks whether AI engines can reach, read and quote your pages. It is a technical exercise, not a strategic one.
The distinction matters because the word audit gets used for two different jobs. One asks where you stand against competitors and which sources own your category. The other asks whether your own site is even in a state to compete. This is the second, and it should come first, because a page an engine cannot fetch scores zero on every strategic measure.
Where it falls short. Passing all twelve checks does not make you visible. It makes you eligible. Visibility comes from authority and content quality, which no technical checklist produces, and which we cover in the GEO best practices playbook.
Group one: access, checks 1 to 4
Free, fast, and the only group where failure invalidates everything else.
1. Are the search crawlers allowed in robots.txt?
The crawler that fetches pages for AI answers is not the same agent as the one that gathers training data, and they are frequently confused.
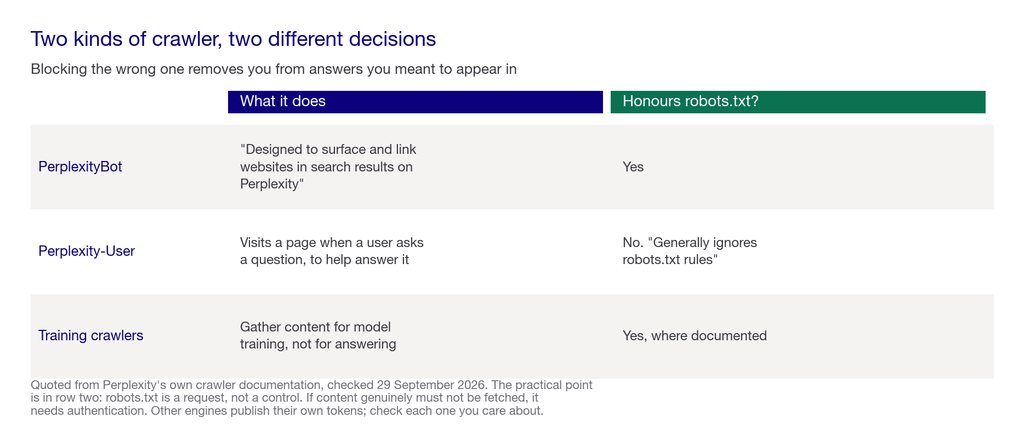
- Perplexity documents two. PerplexityBot is “designed to surface and link websites in search results on Perplexity. It is not used to crawl content for AI foundation models.” That is the one you want allowed.
- Perplexity-User is the other. It “supports user actions within Perplexity. When users ask Perplexity a question, it might visit a web page to help provide an accurate answer.”
- Open your robots.txt and read it line by line. A blanket disallow added during a training-data debate is the most common cause of silent invisibility.
Engine-by-engine differences are covered in how to optimize for ChatGPT and Perplexity.
What good looks like: search crawlers explicitly allowed, training crawlers whatever you have decided, and the decision written down so the next person does not reverse it by accident.
2. Do you know which of your blocks are actually enforced?
Not every fetcher honours robots.txt, and Perplexity says so plainly about one of its own: the user-triggered fetcher “generally ignores robots.txt rules,” because a user request initiated it.
What to do with that. Do not rely on robots.txt as a security or licensing control. It is a request. If content genuinely must not be fetched, it needs authentication, not a directive.
3. Does your answer survive without JavaScript?
Fetch a key page and look at the raw HTML rather than the rendered view. If the paragraph that answers the page’s main question only appears after JavaScript runs, assume some engines will not see it.
How to check in a minute: view source, then search the raw HTML for the first sentence of your answer. If it is not there, it may not be there for an engine either.
4. Are you returning real status codes?
A soft 404, where a missing page returns HTTP 200 with an error message in the body, is common and quietly corrosive. Crawlers treat it as a real page.
How to check: request a URL you know does not exist and look at the status code, not the page. If it returns 200, you have a soft 404 problem. This is worth checking even on sites you assume are fine; we have found it on well-built modern stacks, including on sites whose framework does this by default.
Group two: retrieval, checks 5 to 7
Your pages are reachable. Now, are they usable.
5. Are your preview controls working against you?
Google’s preview directives, nosnippet, data-nosnippet, max-snippet and noindex, all limit how your content can appear in its AI features.
The trap. Teams often set an aggressive max-snippet years ago to stop competitors scraping summaries. That directive is still there, and it now limits your appearance in AI Overviews and AI Mode too.
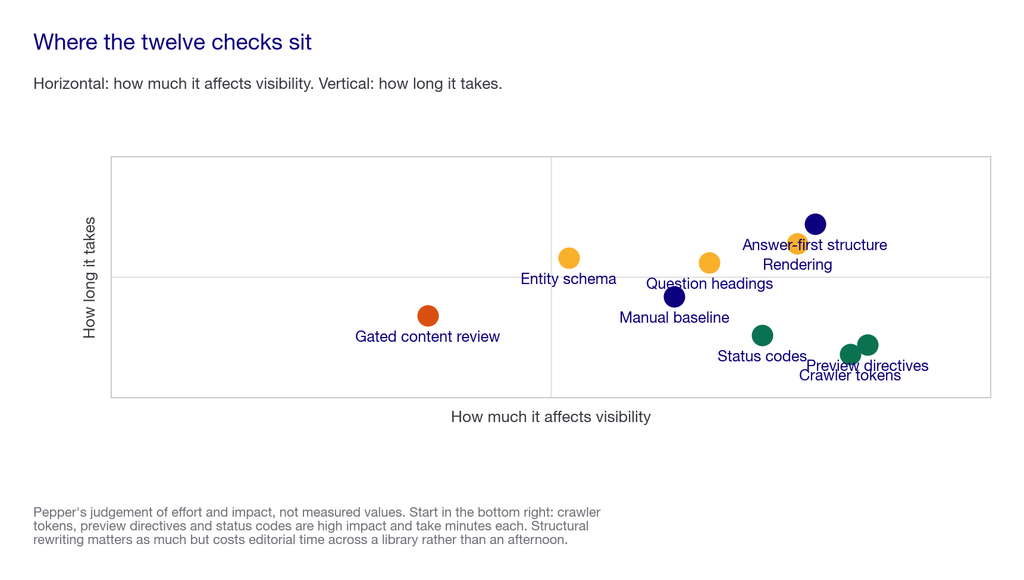
What to do: audit every template for these directives and confirm each one is deliberate. This takes minutes and is the highest-value check in this group.
6. Is anything important sitting behind a form or a login?
Content an engine cannot reach without credentials does not exist as far as AI search is concerned. Gated content is a legitimate business decision, and you should know the visibility cost you are accepting.
If you are auditing a large estate rather than a site, the crawl-scale version is in the enterprise SEO audit framework.
The practical question: for each gated asset, is there an ungated page that carries the same claim in a citable form?
7. Can each page be understood on its own?
Engines lift passages, not sites. A page that only makes sense after reading three other pages will not survive extraction.
What to check: does each key page define its own terms, name its own subject rather than relying on “this approach” or “the platform”, and stand alone if a reader arrives cold?
Group three: structure, checks 8 to 10
Reachable and usable. Now, is the answer liftable.
8. Does the answer come first?
Under every heading, the first two sentences should answer that heading completely.
How to test it: delete everything under a heading except the first two sentences. If what remains still answers the heading, the structure is right. Most pages fail this on first inspection.
9. Are your headings shaped like the questions people ask?
A heading that matches a real query is free retrievability. “Pricing models” becomes “What does it cost?”
The metrics this feeds are defined in AI search visibility metrics and KPIs.
What to check: scan your H2s. How many are topic labels rather than questions? On most sites the answer is nearly all of them.
10. Is your schema doing something that still exists?
Structured data is still worth having, for a narrower reason than it is usually sold.
- Still earning a rich result: Article, Organisation, Product and the other live types. Keep and maintain these.
- No longer shown: FAQPage and HowTo. Google’s documentation states the FAQ rich result “is no longer shown in Google Search results” and that the HowTo rich result “is no longer shown in search results, on both desktop and mobile devices.”
- What to do: leave dead markup in place if it is already there, since it is harmless, but stop maintaining it and stop buying it as a deliverable.
The full picture on which techniques survived is in answer engine optimization techniques.
Group four: evidence, checks 11 to 12
The site is in order. Now, can you see anything.
11. Are you appearing in Google’s generative AI report?
Google publishes a generative AI performance report in Search Console covering AI Overviews and AI Mode. It reports impressions only, defined as “how many times links to your site were shown to a user in a generative AI feature.”
What to look for: whether you appear at all, and which pages carry the impressions. Not all properties have access yet, and a site needs enough impressions in these features to qualify.
What it will not tell you: clicks, position, or which query produced the impression. Its limits are covered in how to know if AI search is sending you traffic.
12. Do you have a baseline outside Google?
Google’s report covers Google’s own surfaces. It says nothing about ChatGPT, Perplexity or Claude.
The minimum viable version: take your twenty most valuable buyer questions, run them in two engines, and record whether you were mentioned and whether a page of yours was cited. That is a baseline, it takes an afternoon, and it costs nothing. The tooling that automates it is compared in top AI visibility platforms.
Working through the twelve in one sitting
Two hours, in this order.
- First thirty minutes, checks 1 to 4. robots.txt, the enforcement caveat, raw HTML, status codes. These are yes-or-no and they gate everything.
- Next twenty minutes, check 5. Template-level audit of preview directives. Highest value per minute on the whole list.
- Next thirty minutes, checks 6 to 10. Sample five important pages rather than auditing everything. Patterns repeat.
- Final forty minutes, checks 11 to 12. Search Console, then twenty prompts by hand in two engines.
Where it falls short as a process. Sampling five pages tells you about your templates, not your library. If the five disagree with each other you have a consistency problem and the audit needs to widen. And none of this measures whether anyone is citing you, which is the strategic question the GEO audit answers.
What nobody should promise you
- That passing the audit makes you visible. It makes you eligible. Authority and content quality do the rest.
- A guaranteed citation in an AI answer. Nobody controls what a model outputs, and we will not promise it either.
- That robots.txt controls access. One documented fetcher ignores it by design. Use authentication if something genuinely must not be fetched.
- Rich results from FAQ or HowTo markup. Google states neither is shown any more.
- A technical fix for a coverage problem. If engines can reach you and still do not cite you, the problem is not on your server.
Frequently asked questions
How do I audit my site for AI search?
Work through four groups in order: access, whether crawlers can fetch you; retrieval, whether your content is usable; structure, whether an answer can be lifted; and evidence, whether you can measure any of it. The first four checks gate the rest.
Which crawlers should I allow for AI search?
Allow the search crawlers, which fetch pages to surface and link them, and decide separately about training crawlers. Perplexity distinguishes PerplexityBot, for search results, from its user-triggered fetcher, which visits pages when someone asks a question.
Access and indexation
Does robots.txt control AI crawlers?
Not all of them. Perplexity states its user-triggered fetcher “generally ignores robots.txt rules,” because a user request initiated the fetch. Treat robots.txt as a request rather than a control, and use authentication where it matters.
What is a soft 404 and why does it matter?
A missing page that returns HTTP 200 with an error message in the body rather than a 404 status. Crawlers treat it as a real page, which wastes crawl budget and pollutes your index. Request a URL that does not exist and check the status code.
Could my own settings be hiding me?
Yes, and this is common. The nosnippet, data-nosnippet and max-snippet directives limit how your content appears in Google’s AI features. An aggressive max-snippet set years ago to deter scrapers now limits you in AI Overviews too.
Structure and measurement
Does schema markup still help AI search?
Entity markup like Article and Organisation is worth maintaining. FAQPage and HowTo are not: Google states neither rich result is shown any more. Existing markup is harmless, but stop treating it as a visibility deliverable.
How do I know if AI engines can read my content?
View the raw HTML rather than the rendered page, then search it for the first sentence of your answer. If the answer only exists after JavaScript runs, assume some engines will not see it.
What is the minimum measurement setup?
Search Console’s generative AI report for Google’s surfaces, plus twenty of your most valuable buyer questions run by hand in two engines, recording whether you were mentioned and whether your page was cited. Both are free.
Sources
Engine and search documentation was read directly on 29 September 2026.
Engine and search documentation
- Perplexity, Crawler documentation, checked 29 September 2026. States PerplexityBot is “designed to surface and link websites in search results on Perplexity. It is not used to crawl content for AI foundation models,” and that Perplexity-User “supports user actions within Perplexity. When users ask Perplexity a question, it might visit a web page to help provide an accurate answer,” noting that fetcher “generally ignores robots.txt rules.”
- Google Search Central, AI features and your website, checked 29 September 2026. Source of the preview controls, nosnippet, data-nosnippet, max-snippet and noindex, and of the statement that there are “no additional requirements to appear in AI Overviews or AI Mode, nor other special optimizations necessary.”
- Google Search Central, FAQ (FAQPage) structured data, checked 29 September 2026. States “The FAQ rich result feature is no longer shown in Google Search results.”
- Google Search Central, HowTo structured data, checked 29 September 2026. States “this rich result is no longer shown in search results, on both desktop and mobile devices.”
- Google Search Console Help, Generative AI performance report (Search), checked 29 September 2026. Covers AI Overviews and AI Mode, reporting impressions defined as “how many times links to your site were shown to a user in a generative AI feature,” with no click metric and no query-level filtering.
On what this checklist is
The four-group ordering and the twelve checks are our own, built from running this work rather than from a published standard. No such standard exists. Every factual claim about crawler behaviour, preview directives and structured data is quoted from the engine’s or Google’s own documentation, and where we assert a time estimate or a priority it is our judgement, not a measurement.
Latest Blogs
Most advice on this is inference dressed as fact. OpenAI documents exactly one thing clearly, which is access. Here is what is documented, what is inferred, and how to verify the rest for yourself.
Being named in an AI answer and having your page used as its source are different outcomes with different causes and different fixes. The gap between them is the most useful diagnostic in AI search, and most reporting collapses it into one number.
Every platform reports share of voice and almost none of them define it the same way. Here is the definition worth using, the three choices that change the number, and how to measure it yourself without buying anything.
Get your hands on the latest news!