AI visibility trackers: tools that monitor brand mentions across AI engines
The short answer
Here is the thing nobody tells you before you buy one. An AI visibility tool is polling, not analytics.
It does not observe what happened. It asks a list of questions on a schedule and writes down what came back. Every confusion about this category follows from that one fact. It is also why two tools give you different numbers for the same brand in the same week.
Key takeaways
- These tools sample, they do not measure. A reading is a survey of what engines said when asked, not a record of what users saw.
- Answers move between runs. One reading is a data point rather than a number, and refresh frequency matters as much as prompt count.
- You choose the questions. The output is only as representative as the prompt set somebody wrote.
- Nobody can see inside Microsoft 365 tenants. Copilot usage there is invisible to every external tool, ours included.
- The two numbers that matter are named and cited, tracked separately. A blended score hides the gap that tells you what to fix.
Where this comes from. We build one of these tools, and we run organic for more than 250 enterprises at Pepper while tracking over 10 million prompts across every major engine. The view below is shaped by that, by the client reviews we sit in every week, and by the conversations we have with buyers at the events we run. So treat it as our read rather than a neutral survey. Prices and engine counts were read from each vendor’s own pricing page on 4 September 2026.
What is an AI visibility tool?
An AI visibility tool runs a defined set of questions against AI engines on a repeating schedule. It records the answers, then reports whether your brand appeared and whether your pages were cited.
That is the whole mechanism. It matters because it is genuinely different from how web analytics works:
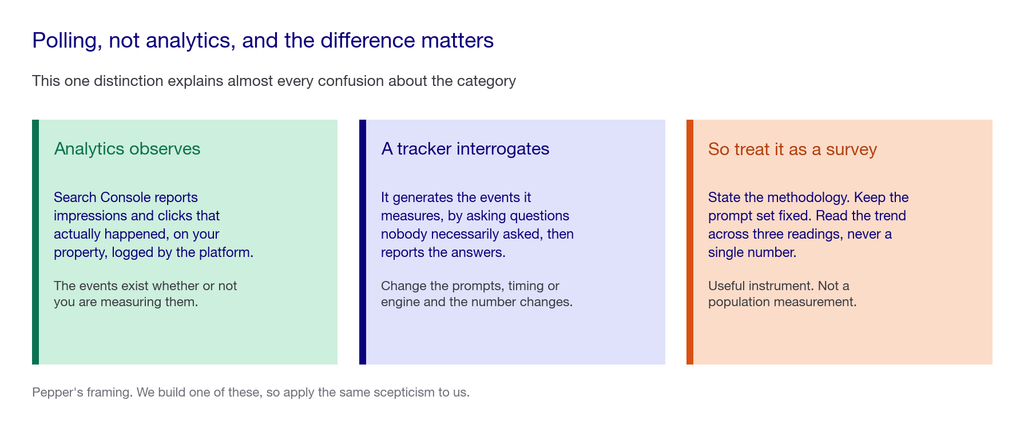
- Analytics is observational. Search Console reports impressions and clicks that actually happened on your property, logged by the platform.
- A visibility tracker is interrogative. It generates the events it measures, by asking questions nobody necessarily asked. Then it reports the answers as if they were a population.
- The consequence is sampling error. Change the prompts, the timing or the engine and the number changes, without anything about your brand changing. The free version of the same method is in how to measure AI search visibility without expensive tools.
None of this makes the category useless. It makes it a survey instrument, and survey instruments need their methodology stated. If you want the underlying discipline first, what GEO is covers it.
See where you show up. Pepper’s GEO platform tracks Brand Visibility, Domain Prompt Presence and Share of Voice across ChatGPT, Perplexity, Gemini, Claude and Google AI Overviews. Your team can log in, connect Search Console and GA4, manage the prompt set and run your own agents in the Agent Atlas. A growth team works the same account alongside you. Book a growth audit or see where you show up.
How an AI visibility tracker actually works
Four stages, and every tool in the category does the same four. The differences are in the parameters, not the mechanism.
- You define a prompt set. Usually 15 to 500 questions depending on what you pay. This is the most consequential input, and the one most teams think least about.
- The tool runs them on a schedule. Daily on some plans, weekly on others. The same plan price can mean very different things depending on which.
- It records what came back. Whether your brand was named, whether a page on your domain was cited, which competitors appeared, and which sources the engine used.
- It compares readings over time. This is where the value is. A single run tells you almost nothing, because engine answers vary. Three runs on a fixed set start to show direction.
The fourth stage is the one people skip, and it is the only one that produces a defensible number.
What these tools genuinely cannot see
Worth stating plainly, because the marketing rarely does.
- Actual user queries. The tool asks your prompts, not what real buyers typed. If your prompt set is wrong, your data is precisely wrong.
- Microsoft Copilot inside enterprise tenants. Much Copilot usage happens inside Microsoft 365 accounts no external tool can observe. Any vendor quoting a precise Copilot figure is estimating, and that includes us.
- Why you were or were not cited. Tools report the outcome. The reason lives in the sources the engine chose, which you have to read yourself, then work. We covered that in LLM seeding.
- Personalised and regional variation. Answers differ by location, account history and session. A tracker sees its own vantage point, not everyone’s. This is one reason a single AI visibility score is worth so little on its own.
- What happened before you started. There is no historical backfill in this category. The day you start tracking is the earliest data you will ever have. That is the honest argument for starting sooner rather than buying more later.
Engine coverage, and why it decides more than price
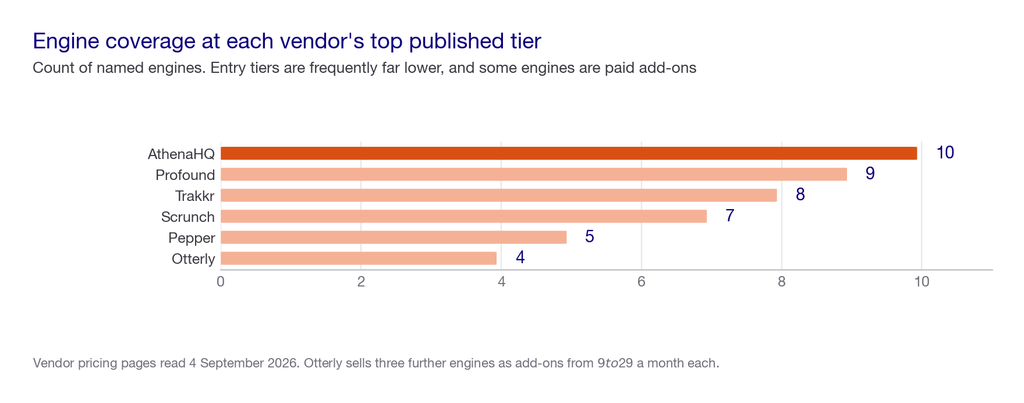
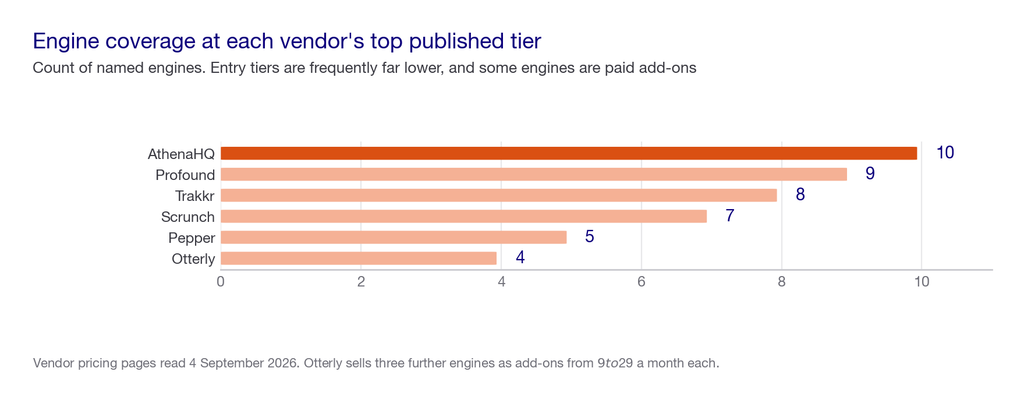
Coverage varies more than any other parameter, and the headline number often excludes paid add-ons.
Verified on each vendor’s own pricing page on 4 September 2026, at the top published tier:
- AthenaHQ: 10 models on its Starter plan, and 5 on the free Essential tier.
- Profound: up to 9 answer engines on Enterprise, but ChatGPT only on its $99 Starter plan.
- Trakkr: all 8 models included on every tier, which is unusual.
- Scrunch: 7 named engines, including Google AI Mode and Meta.
- Otterly: 4 as standard, with Claude, Gemini and Google AI Mode sold as add-ons from $9 to $29 a month each.
- Pepper: 5 engines, being ChatGPT, Perplexity, Gemini, Claude and Google AI Overviews.
Two things follow. Engine count at the entry tier is frequently far lower than the headline. And a four-engine tool selling three more as add-ons is not a four-engine tool at the advertised price.
The engines also differ in how often they cite anyone at all, which is why a blended figure across engines is close to meaningless. We compared them properly in the top AI search engines. Muck Rack’s May 2026 analysis of more than 25 million cited links found ChatGPT carries a citation in 96 percent of responses, Gemini 82 percent, and Claude 55 percent.
Where Pepper sits, honestly
We build one of these, so apply the same scepticism you would to any vendor writing this article.
Pepper is a GEO platform with a growth team attached. It tracks Brand Visibility (how often engines mention you), Domain Prompt Presence (how often they cite a page you own) and Share of Voice (your slice of category mentions), across five engines. Customers log in and run it themselves, and our agentic engine runs the work the tracking points at.
- Where that is the right fit: when the bottleneck is not seeing the gap but closing it, and nobody internally has the hours.
- Where it is not, stated plainly: if you want the cheapest dashboard and already have a capable team, buy Otterly at $29 or Trakkr at $100. Trakkr includes eight models on every tier, which is better raw coverage per dollar than we sell. We would say so on a call.
- Where we are equally blind: Copilot inside enterprise tenants, personalised variation, and the reason behind any individual citation. Nobody in this category has solved those.
For the ranked comparison with prices normalised per tracked prompt, see AI search monitoring tools. For what you can do without paying anything, see the best free AI search tools.
Our methodology: how we weighted what matters in a tracker
| Criterion | Weight | What that means here |
|---|---|---|
| Prompt set quality and control | 30% | You choose the questions, and they represent real buyer language rather than keywords |
| Engine coverage after add-ons | 25% | Named engines at the price you will actually pay, not the headline count |
| Named and cited reported separately | 25% | The gap between the two is the diagnostic. A blended score destroys it |
| Refresh frequency and history | 20% | Daily against weekly is a different product, and exported history is what makes it defensible |
AI visibility tools at a glance
| Tool | Entry price | Prompts at entry | Engines at top tier | Best at | Where it falls short |
|---|---|---|---|---|---|
| Otterly | $29/mo | 15 | 4, plus paid add-ons | Cheapest genuine ongoing entry | Three major engines cost extra, so headline coverage misleads |
| Trakkr | $100/mo | 50 | 8 on every tier | Raw model coverage per dollar | Monitoring only, one brand at entry, and a trial rather than a free tier |
| Profound | $99/mo | 50 | Up to 9 on Enterprise | Enterprise depth and agent analytics | Entry tier is ChatGPT only, which is thin in 2026 |
| Scrunch | $250/mo annual | Not published | 7 named | Agent traffic monitoring and page audits | No published prompt allowance, so you cannot price-compare it |
| AthenaHQ | Free, then $295/mo | Credits, not prompts | 10 paid, 5 free | A genuinely free entry point | Credit pricing is hard to budget against |
| Pepper | Custom | Custom | 5 | Tracking plus the team and agents that act on it | Not the right buy if you only want a cheap dashboard |
Prices and counts read from each vendor’s own pricing page on 4 September 2026. This category repackages often, so confirm before committing.
How to choose an AI visibility tool
The decision is mostly settled by two numbers you can write down in an afternoon: how many prompts you genuinely need tracked, and which engines your buyers actually use.
The scorecard
Score each candidate out of 100.
| Factor | Weight | How to score it honestly |
|---|---|---|
| Prompt allowance against your real set | 30% | Count the questions you actually want tracked first, then check the tier. Fifty prompts is a demo, not a programme |
| Named engines at your price | 25% | Price the engines your buyers use, including add-ons, rather than the headline count |
| Named and cited as separate numbers | 20% | If they are blended into one score, you lose the ability to tell awareness from extractability |
| Refresh frequency | 15% | Daily and weekly are different products at the same price, and not everyone publishes it |
| Export and exit | 10% | You can get your history out, because a year of tracking you cannot export is a year you will repeat |
The live test, over 90 days
Before any demo, write 30 prompts in your buyers’ words. Real questions, such as “what tools track AI search visibility”, “which AI visibility tool covers Claude and Perplexity”, “what is the best data observability platform” and “how do I check if ChatGPT mentions my brand”.
Hand the identical list to every vendor on your shortlist and ask each to show you, inside the trial, where you appear today and which sources are influencing the answers you are missing from.
Then run the same 30 yourself, monthly, for 90 days. Three readings is the shortest honest window: one is a snapshot, two could be noise, three shows direction. Keep the set fixed, because changing it resets the comparison.
This does two things. It tells you whether each vendor’s numbers match what you can see yourself, and it stops you buying a prompt allowance you will never fill.
Weak approach versus strong approach
The weaker approach starts with a roundup. Sit four demos, buy the best-looking dashboard, then discover the entry tier covers one engine and your prompts need the tier above.
The stronger approach: count your prompts and name your engines first. Price the shortlist on those two numbers including add-ons. Buy the cheapest tool that clears both, and put the difference into acting on what it shows.
The difference is which end you start from. The weak version starts at the vendor’s framing. The strong version starts at two numbers you can count yourself.
Red flags
- A single blended visibility score. It hides the gap between being named and being cited, which is the entire diagnostic.
- Precise Copilot figures. Enterprise-tenant usage is not externally observable by anyone.
- “Covers all major AI engines” with no list. Coverage in this category ranges from four to ten, and add-ons change the answer.
- Prompt counts quoted without refresh frequency. Fifty prompts daily and fifty weekly are different products.
- A demo run on the vendor’s prompts. It is measuring their sample, not your buyers.
- Guaranteed citations or visibility scores. Nobody controls generated output, and Google warns against providers guaranteeing rankings.
Five questions worth asking
- “How many prompts, on which named engines, refreshed how often?” Three numbers. Anything vaguer is marketing.
- “Which engines cost extra?” This is where headline coverage comes apart.
- “Do you report named and cited separately?” If they are combined, you lose the diagnosis.
- “How many runs per prompt, and do you show variance?” One run per prompt is a sample presented as a measurement.
- “What can you not see?” Every honest vendor has a list. Ours starts with Copilot inside tenants.
Reduced to one principle: buy on prompt allowance and named engine coverage, then spend what you saved on acting.
One closing note that costs us something. Everything these tools produce is a survey of what engines said when asked, ours included. Treat the number as directional, watch the trend on a fixed prompt set, and be suspicious of anyone in this category, us very much included, who presents a single figure as the truth.
What does an AI visibility tool cost?
| What you are buying | Verified 2026 price | What it covers |
|---|---|---|
| Search Console and Bing Webmaster Tools | Free | First-party reporting on Google and Microsoft surfaces |
| Manual prompt tracking | Free, about two hours a month | 30 prompts across three engines in a spreadsheet you control |
| A free baseline | Free credits | AthenaHQ Essential, five engines, enough for one proper reading |
| Entry monitoring | $29 to $100 a month | Otterly Lite or Trakkr Growth |
| Real prompt volume | $189 to $500 a month | Otterly Standard or Premium, Trakkr Scale, Scrunch Growth |
| Enterprise coverage | $399 a month and up | Profound Growth to Enterprise, up to nine engines |
| Platform plus a growth team | Custom | Pepper: tracking, plus the people and agents doing the work it points at |
The first two rows are free and most teams have not switched them on, which makes them the cheapest thing on this page and the most commonly skipped.
What nobody should promise you
Complete coverage of AI search. Copilot inside enterprise tenants is invisible to every external tool, and personalised variation is unobservable.
A precise visibility percentage. These tools sample, and a sample has error bars nobody in the category publishes.
A guaranteed citation or position. Nobody controls generated output, and Google warns against providers guaranteeing rankings.
Historical data from before you started tracking. There is no backfill in this category, which is the one genuine argument for starting early.
When you do not need one of these
The answer that costs us the sale. If nobody in your organisation has time booked to act on what the dashboard shows, you do not need an AI visibility tool yet and we would tell you not to buy one.
Run 30 prompts by hand once a month instead. It costs two hours and produces the same decision, and it forces someone to read the answers rather than skim a chart. Buy software when the manual run stops fitting in an afternoon, or when someone asks for history you did not capture.
Frequently asked questions
What tools track AI search visibility?
The main platforms are Profound, Scrunch, AthenaHQ, Otterly and Trakkr, alongside Semrush’s AI visibility features and Pepper’s GEO platform. All work the same way. They run a defined prompt set against AI engines on a schedule and record whether your brand is named and cited.
How does an AI visibility tool actually work?
It polls rather than observes. You define a set of questions, the tool asks them on a schedule, records the answers and compares readings over time. It is a survey instrument rather than analytics, which is why a single reading tells you very little.
Why do two AI visibility tools give different numbers?
Because they asked different questions at different times on different engines. Engine answers vary between runs, so two tools polling separately will disagree even when both are working correctly.
Can these tools track Microsoft Copilot?
Only partially. Much Copilot usage happens inside Microsoft 365 tenants no external tool can observe, so any precise Copilot figure is an estimate. This applies to every vendor in the category.
What is the difference between being named and being cited?
Being named means the engine mentions your brand in its answer. Being cited means it links a page on your domain as a source. Tracking them separately tells you whether you have an awareness problem or an extractability one.
How many prompts do I need to track?
Start with 30 real buyer questions rather than keywords. That is enough to establish direction and small enough to run by hand, which means you can check any tool’s numbers against your own.
How much does an AI visibility tool cost?
Entry plans run from $29 a month for Otterly Lite to $250 for Scrunch Starter, and AthenaHQ offers a free tier. Prices were read from each vendor’s pricing page on 4 September 2026, and this category repackages often.
Do I need a paid tool if I have Search Console?
Not immediately. Search Console reports Google’s AI surfaces using your own first-party data, and it is free. You need a platform when you want the other engines, more prompts than you can run by hand, or history you did not capture.
Where to go next
Write down two numbers before you open another vendor site: how many prompts you actually want tracked, and which engines your buyers use.
Then run those prompts by hand once. You will have a baseline no tool can give you retrospectively, and something real to check every vendor’s numbers against.
Learn AI Search · Explore Pepper’s platform · Book a growth audit
Sources and further reading
- Vendor pricing pages, all read 4 September 2026: Otterly (Lite $29 with 15 prompts, 4 engines, add-ons $9 to $29), Trakkr (Growth $100 with 50 prompts, 8 models on every tier), Profound (Starter $99 with 50 prompts ChatGPT only, Enterprise up to 9 engines), Scrunch (Starter $250 annual, 7 named engines, prompt allowance not published) and AthenaHQ (free Essential with 5 engines, Starter $295 with 10 models).
- Muck Rack. “What Is AI Reading?” May 2026. More than 25 million cited links across ChatGPT, Claude and Gemini. Source of the 96, 82 and 55 percent citation-rate figures. Link
- Google Search Central. AI search optimisation guidance, 15 May 2026. Warns against providers guaranteeing rankings.
- Pepper. AI search monitoring tools compared on price per tracked prompt, and the free options.
- Pepper. How to measure AI search visibility without expensive tools, for the manual method referenced throughout.
- Deliberately excluded: any figure for the share of Copilot usage occurring inside enterprise tenants, and any vendor’s own accuracy or coverage benchmark. Neither is externally checkable.
Latest Blogs
Most advice on this is inference dressed as fact. OpenAI documents exactly one thing clearly, which is access. Here is what is documented, what is inferred, and how to verify the rest for yourself.
Being named in an AI answer and having your page used as its source are different outcomes with different causes and different fixes. The gap between them is the most useful diagnostic in AI search, and most reporting collapses it into one number.
Every platform reports share of voice and almost none of them define it the same way. Here is the definition worth using, the three choices that change the number, and how to measure it yourself without buying anything.
Get your hands on the latest news!